Every prompt on the Swarms Marketplace can be run against a live model without leaving the page. Open a prompt, select Chat, and you are talking to the model with that prompt already loaded as the system prompt.
That surface started as a message box with a model dropdown. Over the past several weeks it has become a workspace: every parameter the completions API accepts is adjustable, every model the API reports is selectable, replies show what they cost, and the whole thing works on a phone. Along the way we found and fixed two bugs that were silently losing user data.
This post covers everything that shipped, why each change was made, and what is still outstanding.
Conversation Starters, and Why They Took Ten Seconds
An empty chat is a hard place to start. You have opened someone else's prompt, you do not know what it is good at, and the cursor is blinking at you. Swarms Chat now suggests three opening questions specific to the prompt you are looking at, generated by a small agent that reads the prompt itself.
The first version worked but was too slow to matter. The starters agent took about 10.3 seconds. It fires after the page has painted, so it never blocked anything, but the chips landed long after the page was usable, which in practice means after the user had already typed something. A suggestion that arrives once you no longer need it is not a feature.
We benchmarked ten candidate models on the real task, running each two to four times and measuring the median. The results were stark:
| Model | Median | Returned three starters |
|---|
| claude-haiku-4-5 (original) | 10.31s | 4 of 4 |
| gpt-4.1-mini (current) | 2.39s | 4 of 4 |
| gpt-4.1-nano | 2.68s | 4 of 4 |
| gpt-4o-mini | 2.85s | 4 of 4 |
Swapping the model accounts for most of the improvement. Trimming the system prompt from sixteen lines to a much tighter instruction accounts for the rest. End to end, starters now arrive in about 2.9 seconds, roughly 3.5 times faster, and they arrive while you are still reading the page rather than after you have given up on it.
One finding from that benchmarking is worth repeating for anyone building on the Swarms API directly: gpt-5.4 with tools_list_dictionary returns no assistant output at all, which is why the starters agent uses a different model for its tool call.
Full Control of the Agent
The chat header has a settings button that opens a tabbed dialog: Generation, Behaviour, Tools, and Marketplace. It exposes every AgentSpec parameter that POST /v1/agent/completions accepts, with four deliberate exceptions.
agent_name, description, and system_prompt belong to the prompt you are running, so the chat does not let you override them. model_name belongs to the model picker. Everything else, temperature, top_p, max_tokens, max_loops, reasoning effort, tool configuration, is yours to change.
Settings are stored per prompt in local storage, which has a specific consequence worth knowing: tuning one prompt never disturbs another. You can leave a research prompt at high reasoning effort and a drafting prompt at low, and each remembers its own configuration.
Two defaults changed with this work. max_tokens moved from 8192 to 32000, because replies were being truncated on longer tasks. Default reasoning_effort is now low, which requires an explanation: setting reasoning_effort to minimal makes the API return an empty reply, confirmed on both claude-haiku-4-5 and gpt-5.4, and none does the same on Claude. low is the lowest value that reliably produces output. The settings panel still offers minimal, so choosing it will produce empty replies until that is fixed upstream. We would rather document that than pretend it works.
A Searchable Model Picker Covering Everything
The old model dropdown listed a hardcoded subset of models. If the API gained a model, the picker did not know about it.
That dropdown was replaced with a searchable picker, used on both chat surfaces, and it now lists every model the Swarms API reports from GET /v1/models/available. The current list spans GPT-5.4 and later, Claude Sonnet and Opus 5, Kimi K3, GLM-5.3, DeepSeek, Qwen, MiniMax, and the OpenRouter catalog. Every identifier in the picker was verified present in the live API response rather than copied from documentation.
Selection state is green, matching the rest of the platform, and the picker trigger shares a surface with every other header control.
Token Counts on Every Reply
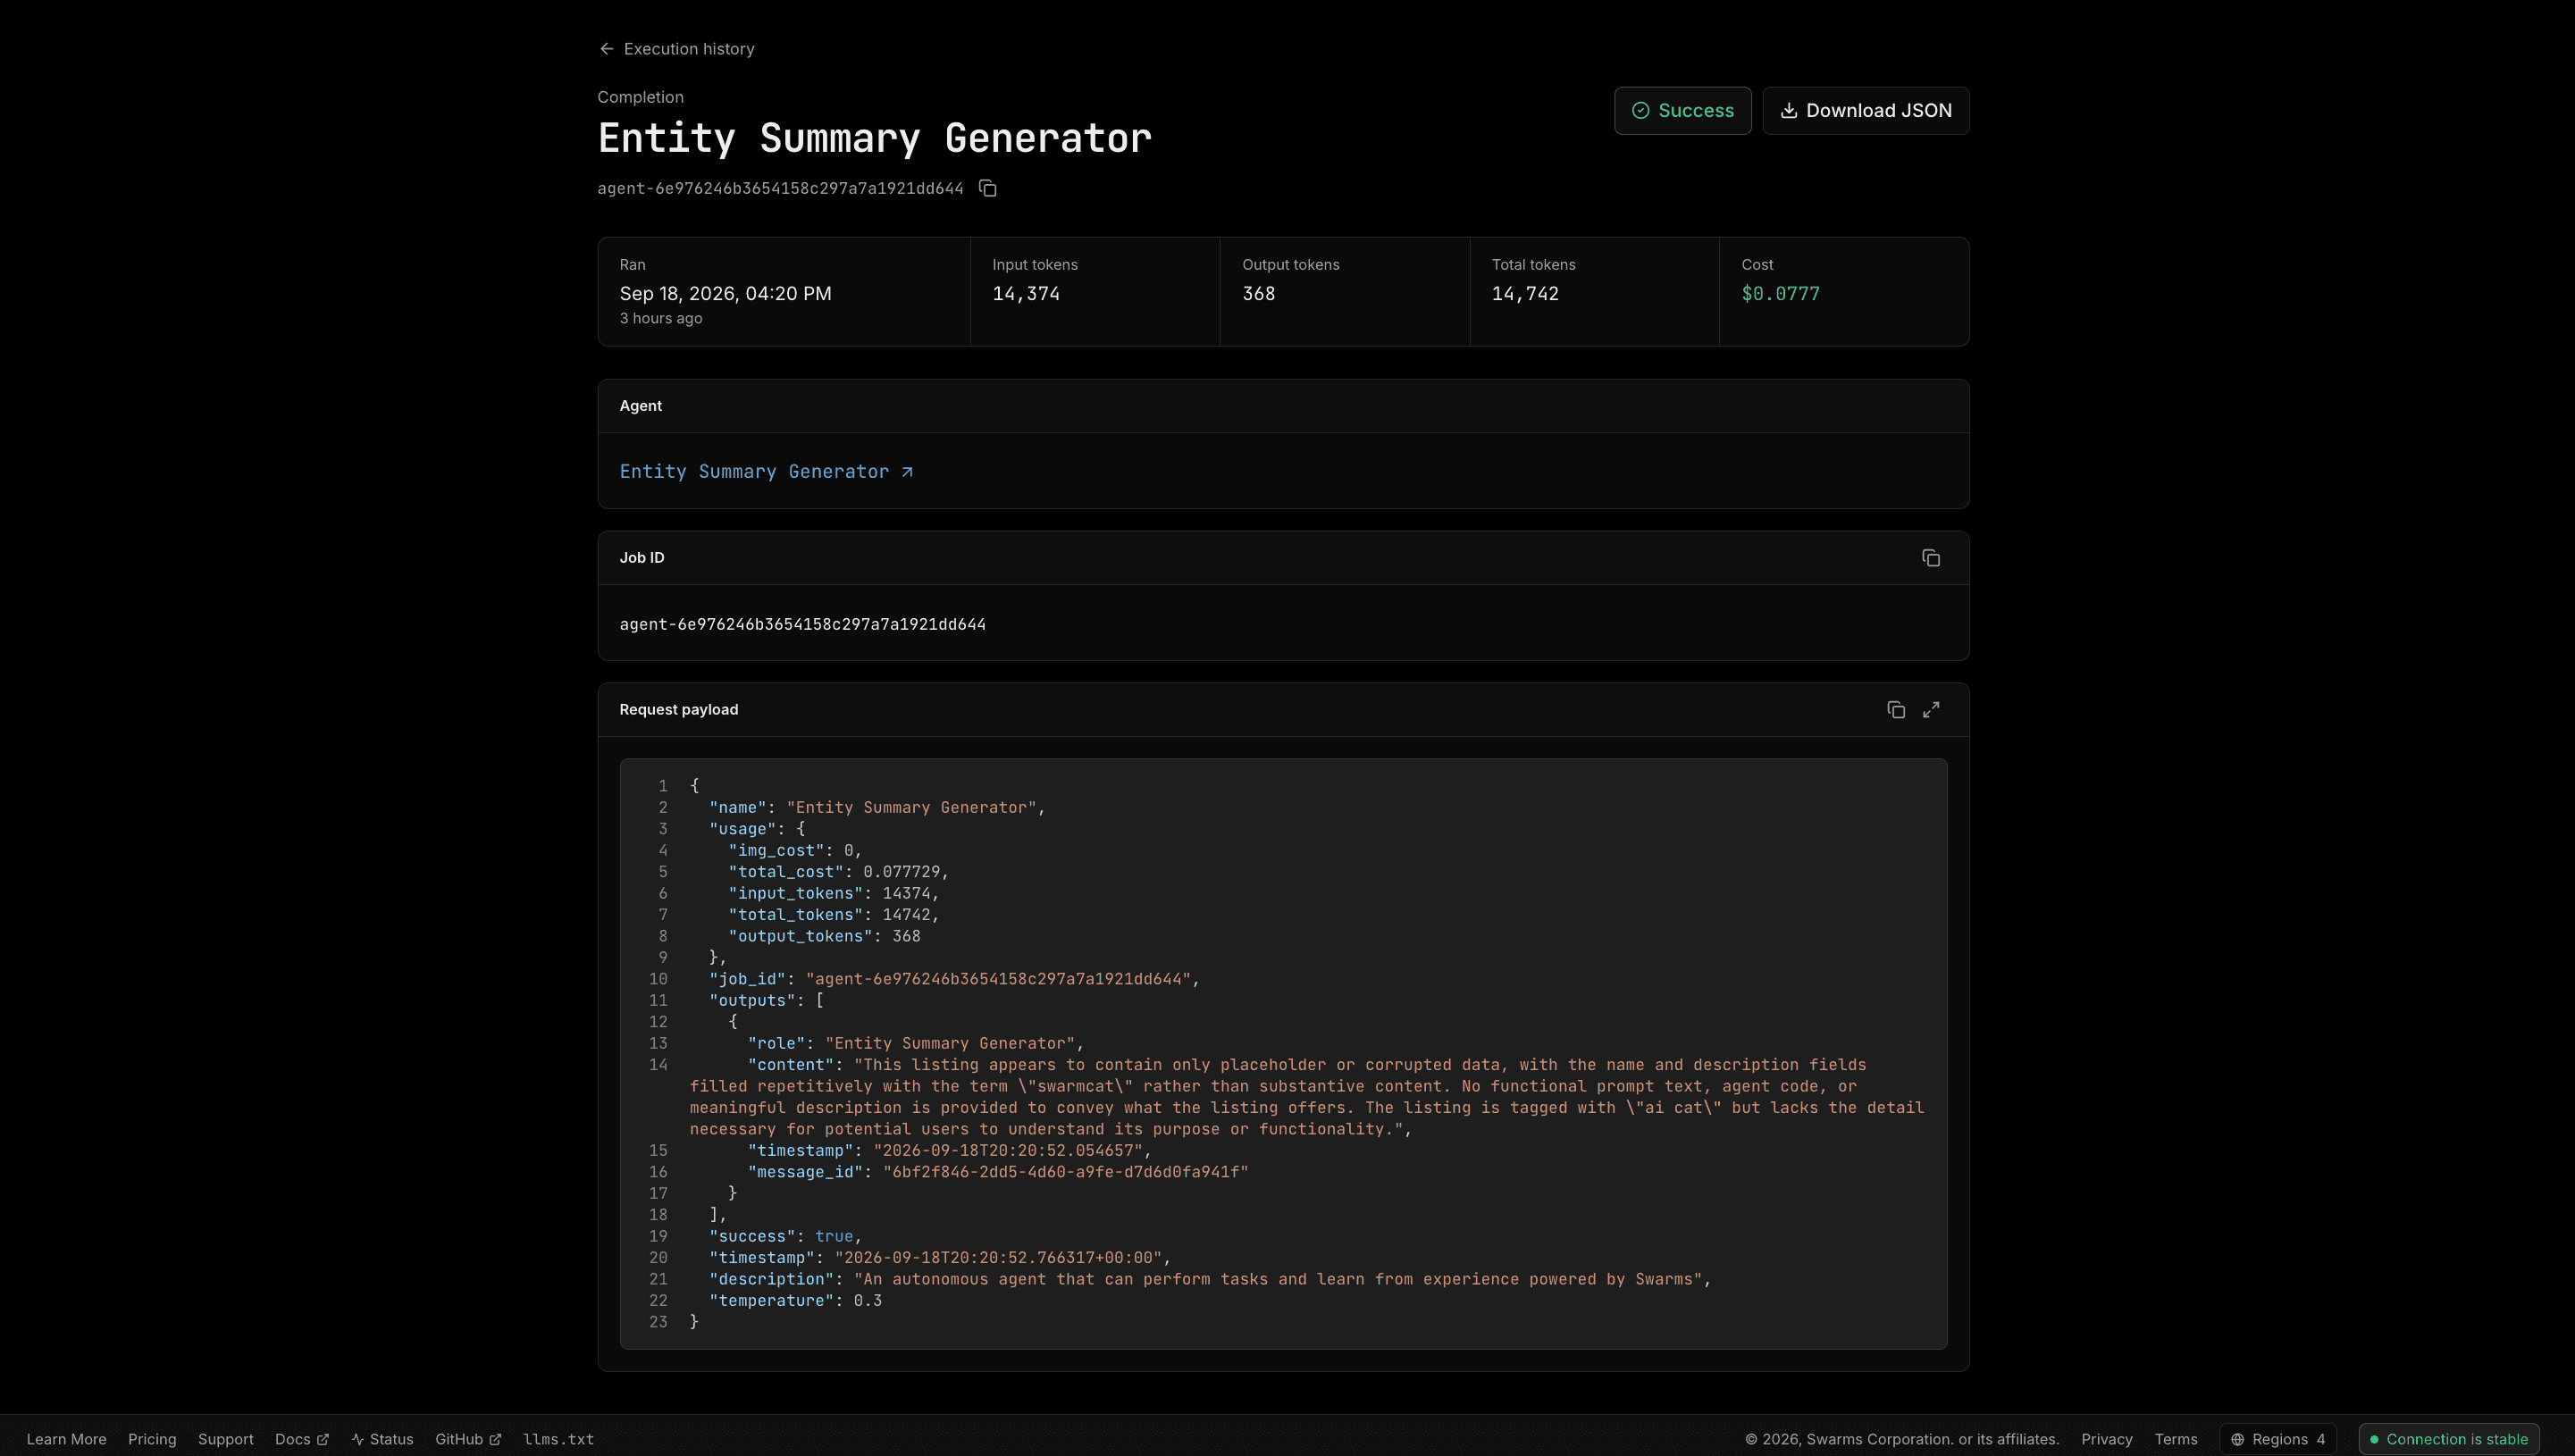
The Swarms completions stream has always sent a usage frame containing input and output token counts. The chat hook read past it and threw it away.
Each assistant reply now shows its output token count beside the copy button, read from that frame rather than estimated client side. It is a small addition that changes how the chat is used: when you can see that a reply cost 4000 tokens, you start noticing which prompts and which settings are expensive, and you tune accordingly.
Retry, Try Another Model, and Continue
Three actions now sit on each assistant message.
Retry re-runs the turn in place. It replaces the reply rather than appending a duplicate, so a conversation you retry three times does not end up with three near-identical answers cluttering the history.
Try another model re-runs the same turn against a different model, with the picker staying in sync with whatever you are actually using. This is the fastest way to find out whether a disappointing answer is the prompt's fault or the model's.
Continue picks up a reply that was cut short, either because you stopped it or because it hit a limit.
All three share one streaming loop internally, which is why they behave identically rather than each having its own quirks.
The Composer
Several changes here, all aimed at the same thing: getting text and images into the chat without breaking your flow.
- Paste a screenshot directly into the composer with Command V.
- Drag and drop files onto the composer, or onto the attach button, which is its own drop target.
- Command Return always sends. A toggle under the composer decides whether a bare Return sends or inserts a newline, because both camps exist and neither is wrong.
- Pressing Up on an empty composer recalls your last message for editing and resending.
Streaming That Behaves
Three fixes that are individually small and collectively make the chat feel different.
A blinking caret sits at the head of the stream, so you can tell the difference between a model that is thinking and one that has stalled. Replies fade in once, gently, rather than snapping into place.
Auto-scroll now releases when you scroll up. Previously, reading back through a conversation while a reply streamed would yank you to the bottom on every chunk. A jump to latest pill appears instead, and you return when you choose to.
The message body is memoized. Composer input state lived in the same hook as the message list, which meant every keystroke re-rendered the entire conversation history through the markdown renderer. On a long chat that is exactly as slow as it sounds.
Two Bugs That Were Losing Data
Only one of four attached images was reaching the model. The chat accepted four image attachments and displayed four thumbnails, but the request body only ever carried the first. The other three were silently dropped. The request now sends the API's imgs array alongside img, and strips data URL prefixes from every image rather than only the first.
There is an important caveat here, and it is upstream of us. We verified against the live API that img as bare base64, as a data URL, as an https URL, and imgs as an array all produce a reply identical to the no-image control. In other words, the API accepts the documented fields and does not currently forward the image to the model. Our side now sends the correct shape. The remaining gap is on the API, and it is being tracked there.
An error toast could crash the page. The error title was built as a chain of fallbacks, and a plain Error object is truthy, so it was selected and handed to the toast, which tried to render an object as a React child and took down the view. Upstream errors are now flattened to strings before they reach the toast.
Mobile
The chat received a full responsive pass rather than a squeeze. Below the medium breakpoint, the header collapses to a back button, the model name, and a single overflow menu holding web search, settings, reset, and fullscreen. The five separate controls that worked on a desktop do not fit on a phone and were not trying to.
The composer, message list, attachment handling, and the settings dialog were each reworked for small screens.
Reliability and Access
A stream that ends without producing any text is now retried without streaming, and the reply is delivered as a single chunk. If it is still empty, the empty bubble is removed and a toast names the model that produced nothing, rather than leaving a blank message in the conversation.
Web search uses the plain completion with max_loops: 2, because the streaming endpoint emits no text during its tool-call loops.
The chat route requires a session and validates the requested model server side, so it cannot be used as an open proxy to arbitrary models.
Consistency
User bubbles in both the prompt chat and the Yuki chat now use the same dark grey as the navbar. Every header control shares one component, one surface, and a hover tooltip naming what it does. Opening a chat from a product page goes straight to fullscreen instead of the embedded view.
What Is Still Outstanding
Three things are known and not yet fixed.
Image attachments reach the API correctly but the API does not forward them to the model. That is upstream.
The settings panel offers reasoning_effort: minimal, which produces empty replies on every model we tested. It should be removed or flagged in the interface.
The assistant avatar insets its bubbles 42 pixels from the composer's left edge. Fixing it means moving the avatar out of the message row, which is a layout change rather than a width adjustment, so it was deliberately left alone.
Try It
Open any prompt on swarms.world and select Chat, or browse the full catalog at swarms.world/platform/registry. API documentation for building against the same completions endpoint is at swarms.world/docs/api.