We ran swarms-rs 0.3.0 head to head against three of the most widely used agent frameworks: Swarms (Python) 15.0.3, LangGraph 1.2.12 and CrewAI 1.15.23. Every framework drove the same model, Claude Sonnet 5.5, through the same agents, the same system prompts and the same tasks.
The results are clear. On every measure a framework controls, swarms-rs comes out ahead, and by a wide margin:
| swarms-rs | Swarms (Python) | LangGraph | CrewAI |
|---|
| Cold start (launch to agent ready) | 6 ms | 2,647 ms | 780 ms | 1,439 ms |
| Memory at startup | 3.7 MB | 250 MB | 94 MB | 179 MB |
| Framework time per LLM call | 0.11 ms | 1.11 ms | 1.77 ms | 9.68 ms |
| 100 agents in parallel (ideal 0.5 s) | 0.52 s | 2.21 s | 0.72 s | 4.20 s |
In short:
- 130x to 440x faster startup. A swarms-rs process is ready to run an agent in 6 milliseconds.
- 25x to 68x less memory. A complete swarms-rs agent process peaks at 3.7 MB.
- 10x to 88x less framework time per LLM call. swarms-rs spends 0.11 ms of its own time around each model call.
- Near-perfect parallelism. 100 agents finish in 0.52 seconds when each call takes 0.50 seconds, which is 97% efficiency, using 29 MB of memory.
This post explains what we measured and why it matters, then walks through each result. The full harness, report and charts are open source in the swarms-rust-benchmark repository, so you can rerun every number on your own machine.
Why framework overhead matters
Every framework in this comparison calls the same model, and Claude takes the same time to generate an answer no matter which framework sent the request. What a framework does control is everything around that call: how long a process takes to start, how much memory each agent costs, how much work happens before and after each request, and how many agents actually run at the same time when you ask for parallelism.
That overhead is easy to ignore in a notebook and hard to ignore in production:
- Serverless and short-lived processes pay the full startup cost on every cold start. A 2.6 second import is 2.6 seconds of latency and billed compute before the first agent does anything.
- High-throughput services pay the per-call overhead on every request. Milliseconds per call add up to whole machines at scale.
- Large swarms multiply both memory and scheduling costs by the number of agents. The difference between 29 MB and 464 MB for 100 agents is the difference between packing many swarms onto one box and needing a fleet.
How we measured
We built the benchmark to be fair to every framework and easy to reproduce.
Identical workloads. Each framework ran three workflows built from its own idiomatic building blocks: a single agent, a three-agent sequential pipeline (Researcher, Analyst, Writer), and N agents fanning out in parallel on one task. All four used the same agent names, system prompts and tasks from one shared file.
| Workflow | swarms-rs | Swarms (Python) | LangGraph | CrewAI |
|---|
| Single agent | SwarmsAgent | Agent | one-node StateGraph | one-agent Crew |
| Sequential | SequentialWorkflow | SequentialWorkflow | three-node chain | Process.sequential |
| Parallel | ConcurrentWorkflow | ConcurrentWorkflow | fan-out from START | Crew.akickoff() per agent |
Identical model settings. Every framework used claude-sonnet-5-5 with max_tokens=4096, no tools and one loop per agent. Every request passed through a local proxy that logged it, so we could confirm from the requests themselves that all four frameworks sent the same settings and made exactly one API call per agent run.
Two suites.
- Framework overhead. The proxy acted as a mock of the Anthropic Messages API that answers instantly, or after exactly 500 ms in the parallel test. With the model and the network taken out of the picture, the only thing left to measure is the framework itself.
- Live runs on Claude Sonnet 5.5. The proxy forwarded every request to the real Anthropic API: 104 API calls across 44 workflow runs, with zero errors in any framework.
Clean environments. Each Python framework was installed in its own virtual environment, so no framework paid for another's dependencies. swarms-rs was built in release mode. Telemetry was switched off in every framework, and one discarded warm-up launch per framework ran before timing started so Python bytecode caches already existed. Peak memory comes from /usr/bin/time -l wrapped around every process.
Everything ran on an Apple M3 Pro (12 cores, 18 GB) with Python 3.12.3 and Rust 1.98.1.
Cold start: 6 ms to a ready agent
We launched each framework's process ten times and measured the time from process launch to a fully constructed agent, along with peak memory.
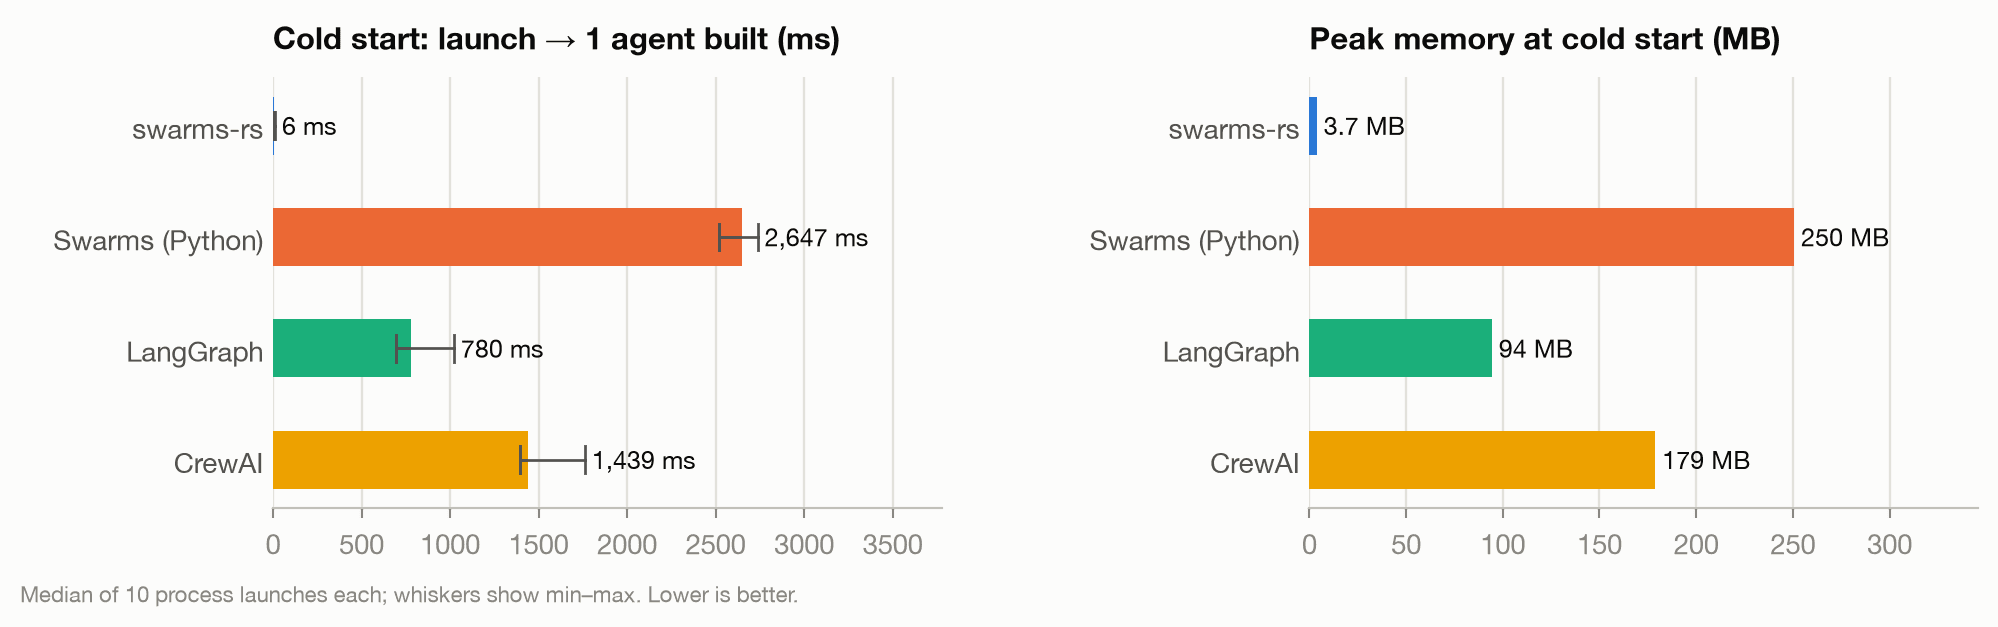
| Launch to agent ready | Framework import | Agent construction | Peak memory |
|---|
| swarms-rs | 6 ms | none (native binary) | 0.01 ms | 3.7 MB |
| Swarms (Python) | 2,647 ms | 2,312 ms | 0.92 ms | 250 MB |
| LangGraph | 780 ms | 624 ms | 1.18 ms | 94 MB |
| CrewAI | 1,439 ms | 1,065 ms | 113.52 ms | 179 MB |
A swarms-rs agent is ready 130x faster than LangGraph, 240x faster than CrewAI and 440x faster than Swarms (Python). The reason is structural. A Python framework has to import its entire dependency graph before it can build an agent, and that import alone takes between 0.6 and 2.3 seconds. swarms-rs compiles to a single native binary, so there is nothing to import, and building an agent is plain struct construction that takes about 10 microseconds.
For serverless functions, CLI tools, CI jobs and autoscaling workers, startup is the latency your users see first. With swarms-rs it effectively disappears.
Memory: 3.7 MB per process
The same runs recorded peak resident memory. A complete swarms-rs process, with the async runtime, HTTP client and a configured agent, peaks at 3.7 MB. That is 25x less than LangGraph (94 MB), 48x less than CrewAI (179 MB) and 68x less than Swarms (Python) (250 MB).
The footprint stays small once real work starts. During the live Claude Sonnet 5.5 runs, including the three-agent pipeline and the parallel workflow, swarms-rs peaked at 4 to 5 MB. The Python frameworks peaked between 98 MB and 252 MB for the same workflows.
Small processes are cheap processes. You can run swarms-rs agents in containers with tight memory limits, on edge devices, or by the hundreds on a single machine.
Framework time per LLM call: 0.11 ms
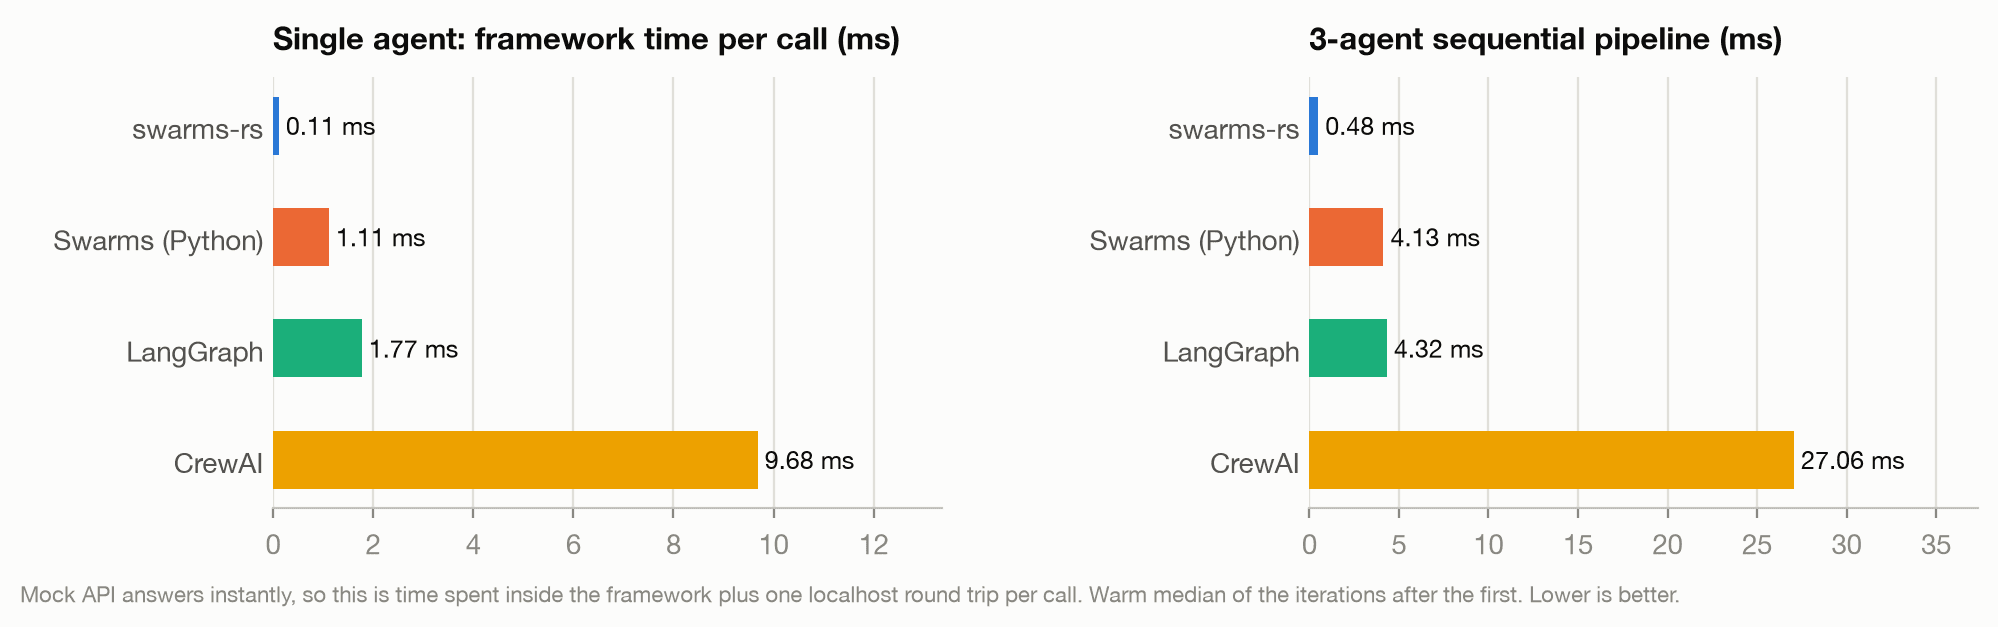
To isolate orchestration cost, we pointed each framework at the mock API that answers instantly and timed 30 consecutive agent runs. What remains is the framework's own work around each call, plus one round trip over localhost that is identical for everyone.
| Per call (warm median) | Per call (p95) | Three-agent pipeline |
|---|
| swarms-rs | 0.11 ms | 0.16 ms | 0.48 ms |
| Swarms (Python) | 1.11 ms | 1.43 ms | 4.13 ms |
| LangGraph | 1.77 ms | 1.95 ms | 4.32 ms |
| CrewAI | 9.68 ms | 19.72 ms | 27.06 ms |
swarms-rs adds 0.11 ms per LLM call, 10x less than Swarms (Python), 16x less than LangGraph and 88x less than CrewAI. A full three-agent sequential pipeline costs 0.48 ms of framework time, 9x to 56x less than the alternatives. The tail stays just as tight: the 95th percentile is 0.16 ms.
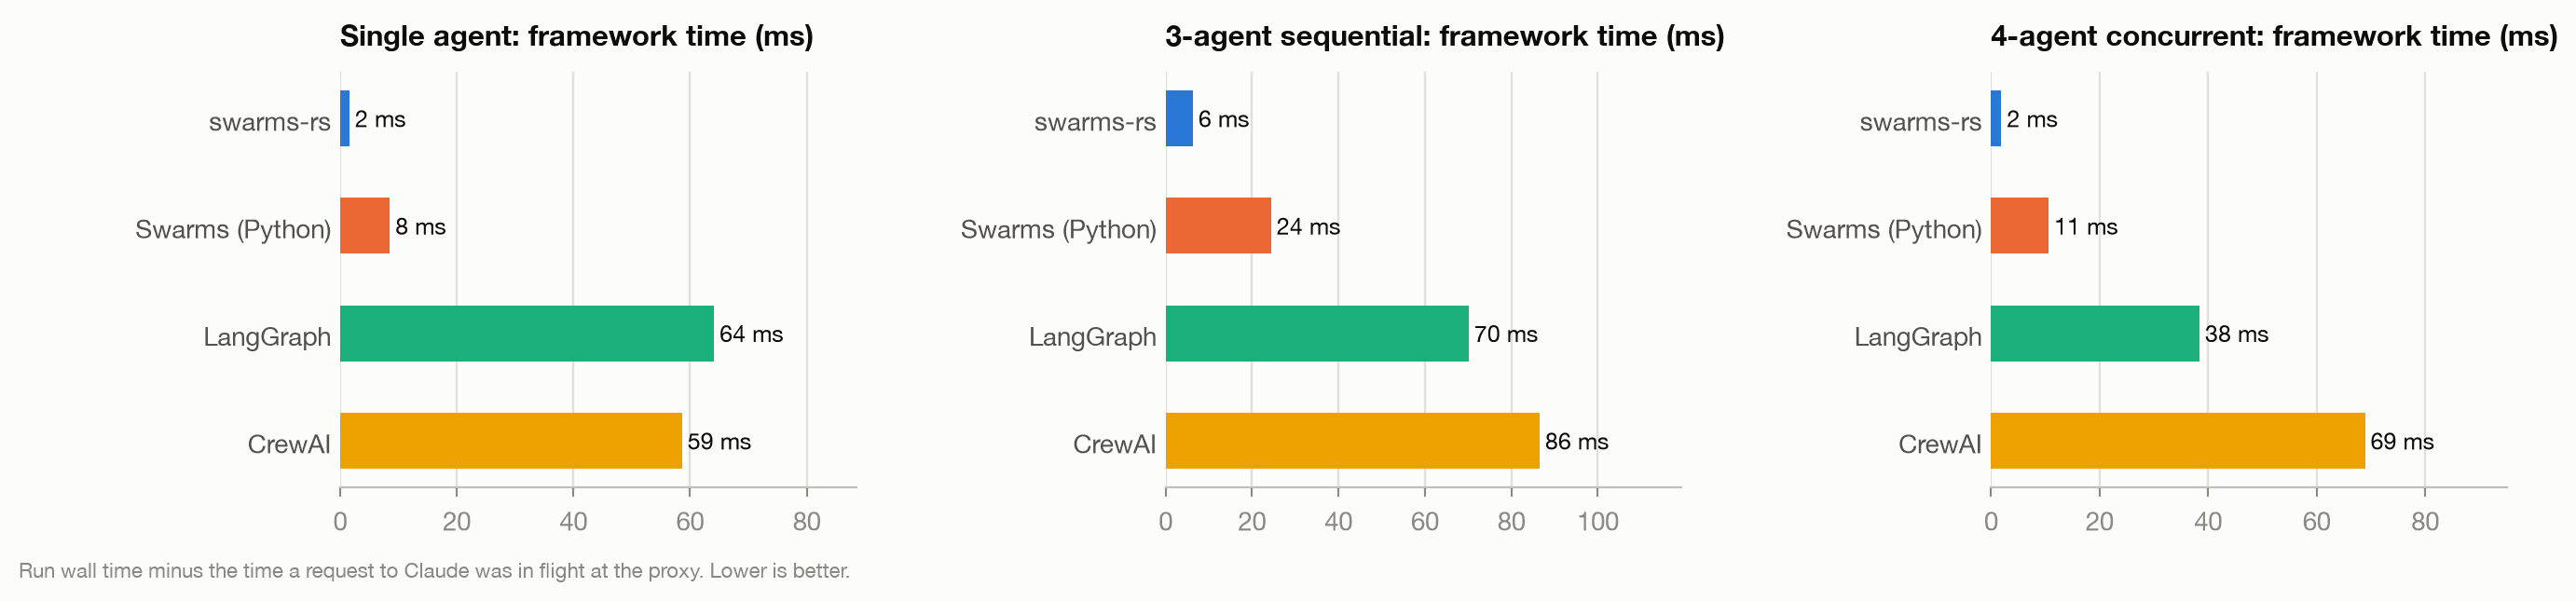
The live runs confirm it. Against the real Claude API, we subtracted the time each request spent at the API from the total run time, which leaves the time spent in the framework on a fresh process:
| Live on Claude Sonnet 5.5 | swarms-rs | Swarms (Python) | LangGraph | CrewAI |
|---|
| Single agent | 2 ms | 8 ms | 64 ms | 59 ms |
| Three-agent sequential | 6 ms | 24 ms | 70 ms | 86 ms |
| Four-agent parallel | 2 ms | 11 ms | 38 ms | 69 ms |
Across every live workflow, swarms-rs spent between 2 and 6 milliseconds of its own time. In practice, a swarms-rs workflow finishes as soon as the model does.
100 agents in parallel: 0.52 seconds
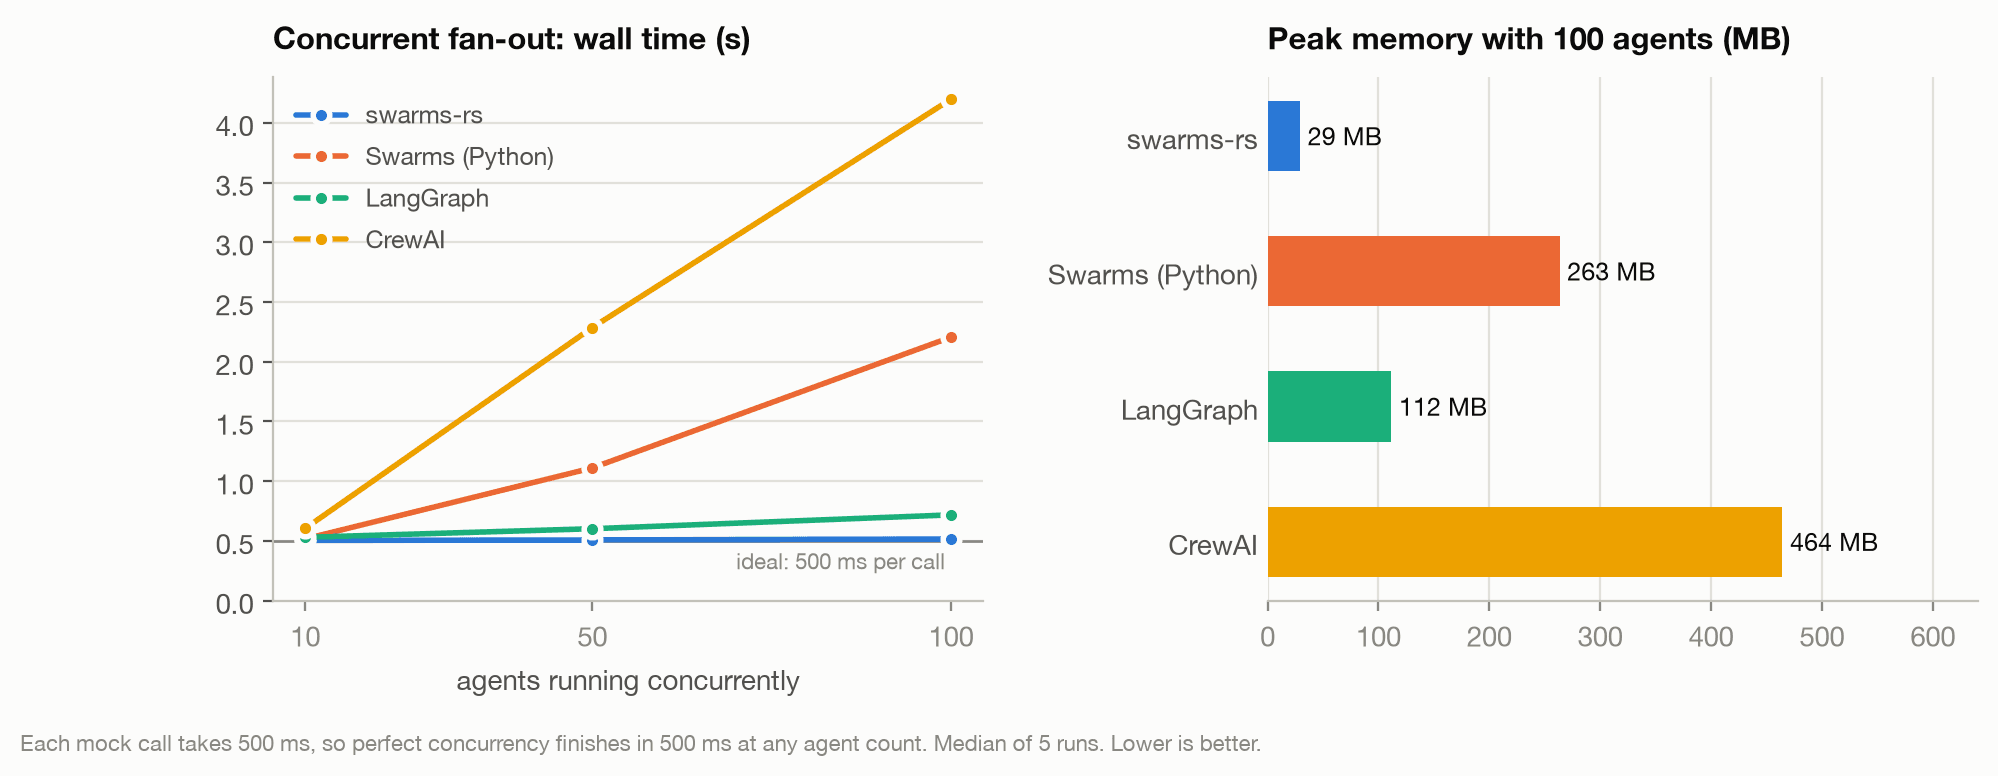
The parallel test is where framework design shows most clearly. We configured the mock API to take exactly 500 ms per call and ran 10, 50 and 100 agents at once on the same task, five runs each. A framework with perfect parallelism finishes in 500 ms regardless of the number of agents.
| 100 agents | Wall time | Parallel efficiency | Peak requests in flight | Peak memory |
|---|
| swarms-rs | 0.52 s | 97% | 100 | 29 MB |
| LangGraph | 0.72 s | 70% | 100 | 112 MB |
| Swarms (Python) | 2.21 s | 23% | 32 | 263 MB |
| CrewAI | 4.20 s | 12% | 16 | 464 MB |
swarms-rs finishes 100 agents in 0.52 seconds, 16 ms from the theoretical ideal, and it holds that line at every size: 0.504 s for 10 agents, 0.508 s for 50 and 0.516 s for 100. It does all of this in 29 MB of memory, 4x to 16x less than the alternatives.
The proxy recorded how many requests each framework actually had in flight at once, which explains the spread:
- swarms-rs sent all 100 requests at once.
ConcurrentWorkflow drives every agent as a lightweight future on the Tokio runtime, so an agent waiting on the network costs almost nothing. The agents are clones of one Anthropic client, so they share a single connection pool.
- LangGraph also reached 100 requests in flight, but each call does enough work on Python's single event loop that efficiency drops to 70% at 100 agents.
- Swarms (Python) runs 32 agents at a time by default, a ceiling that protects provider rate limits. Raising
max_workers lets it go wider.
- CrewAI never had more than 16 requests in flight, so 100 agents run in roughly seven waves.
Parallel agent teams are central to multi-agent systems: panels of experts, map-reduce over documents, and model ensembles all depend on it. swarms-rs scales them up with almost no added time or memory.
What this means for you
If you are building agents that need to start fast, stay small or run wide, swarms-rs removes the framework as a bottleneck:
- Serverless and edge deployments get 6 ms cold starts and single-digit-megabyte processes.
- High-throughput services spend a tenth of a millisecond on orchestration per call, so capacity goes to real work.
- Large swarms run 100 agents in parallel at 97% efficiency in 29 MB.
- Rust services can embed agents directly, with the same agents, workflows and providers as the rest of the Swarms ecosystem.
Reproduce the results
The complete harness is in the swarms-rust-benchmark repository. It includes the shared task file, one benchmark program per framework, the recording proxy, and the script that produces every table and chart in this post. Running the suites writes the raw per-run data and logs to your own machine.
git clone https://github.com/The-Swarm-Corporation/swarms-rust-benchmark
cd swarms-rust-benchmark

for env in swarms langgraph crewai harness; do
  uv venv -q --python 3.12 .venvs/$env
  VIRTUAL_ENV=.venvs/$env uv pip install -r requirements/$env.txt
done

.venvs/harness/bin/python harness/run.py --suite mock   # framework overhead, about 3 minutes, no API cost
.venvs/harness/bin/python harness/run.py --suite live   # real Claude calls, needs ANTHROPIC_API_KEY
.venvs/harness/bin/python harness/compare.py            # tables and charts
Get started with swarms-rs
Add swarms-rs to your project:
cargo add swarms-rs@0.3
cargo add tokio --features full
cargo add anyhow
export ANTHROPIC_API_KEY="sk-ant-..."
Here is the parallel workflow from the benchmark: four analysts reviewing the same proposal on Claude Sonnet 5.5, all at once.
use swarms_rs::{
    agent::SwarmsAgentBuilder,
    llm::provider::anthropic::Anthropic,
    structs::{agent::Agent, concurrent_workflow::ConcurrentWorkflow},
};

#[tokio::main]
async fn main() -> anyhow::Result<()> {
    // Reads ANTHROPIC_API_KEY from the environment.
    let model = Anthropic::from_env_with_model("claude-sonnet-5-5");

    let roles = [
        ("Technical-Analyst", "Evaluate the proposal from an engineering and scalability perspective."),
        ("Financial-Analyst", "Evaluate the proposal from a cost, revenue and unit-economics perspective."),
        ("Risk-Analyst", "Evaluate the proposal from an operational and security risk perspective."),
        ("Regulatory-Analyst", "Evaluate the proposal from a compliance and licensing perspective."),
    ];

    let agents: Vec<Box<dyn Agent>> = roles
        .iter()
        .map(|(name, prompt)| {
            Box::new(
                SwarmsAgentBuilder::new_with_model(model.clone())
                    .agent_name(*name)
                    .system_prompt(*prompt)
                    .max_loops(1)
                    .build(),
            ) as Box<dyn Agent>
        })
        .collect();

    let workflow = ConcurrentWorkflow::builder()
        .name("ProposalReview")
        .agents(agents)
        .build();

    // All four agents call Claude at the same time.
    let result = workflow
        .run("Evaluate launching a stablecoin payments product for small businesses in the EU.")
        .await?;
    println!("{result}");
    Ok(())
}
To go further:
- Read the Swarms Rust v0.3.0 release notes for OpenRouter,
AnyModel, sub-agents and handoffs.
- Browse the API on docs.rs/swarms-rs.
- Star and follow the project on GitHub.